Research
My research is about large multimodal models: how to learn representations that put images and text in one space, and how to train them at scale. At Amazon Visual Search (A9) I led training of the team's CLIP model, which shipped worldwide in multiple Amazon production features, and of a general-purpose embedding model built on a vision-language model. This work brought image-text alignment into Amazon's visual search system (KDD 2024) and used large language models to understand multimodal search queries (CVPR 2024).
Models like these are only as good as the system that trains them. I worked on an internal distributed training platform built on Ray, which delivered two generations of VLM-based models.
More recently I have worked on agents whose work can be checked. I fine-tuned models with LoRA for agentic orchestration of visual search, and as a founder I am now applying agentic AI to IC physical design, where deterministic EDA tool outputs act as the oracle for an agent's work.
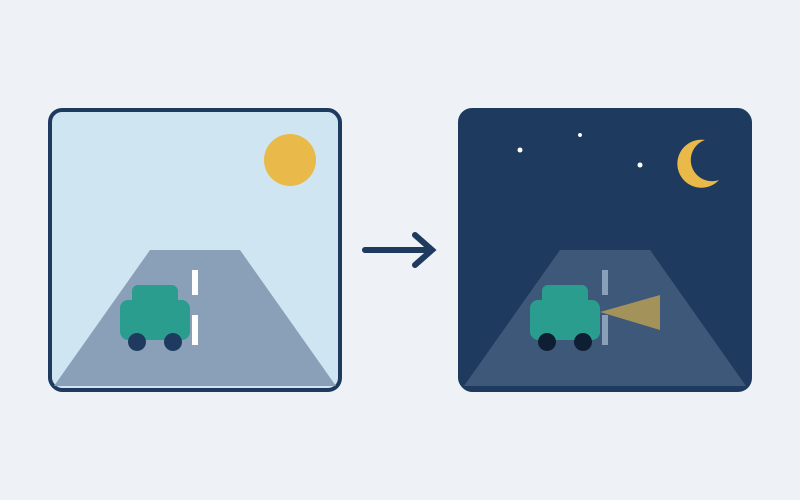
Before Amazon, I worked on computer vision for domains where labelled data is scarce: GAN-based image translation that generates training data for a new domain (ECCV 2018), day-to-night style transfer for nighttime vehicle detection, and indoor scene layout estimation.